Drag, Infer, Reproject: Grounding LLMs through Spatial Interaction for Image Clustering
Yang Liu (Virginia Tech), Xuxin Tang (Virginia Tech), Jiahao Xu (Virginia Tech), Chris North (Virginia Tech)
Presentation
- Session
- Me, Myself, and AI
- Time
- Wednesday, Nov 11, 13:27 – 13:36 (US/Eastern) · session 13:00 – 14:30
- Room
- Hall America center
Links
Sign in to access the Paper PDF.
- Preprint PDF(opens in new tab)
- Supplemental Material(opens in new tab)
Abstract
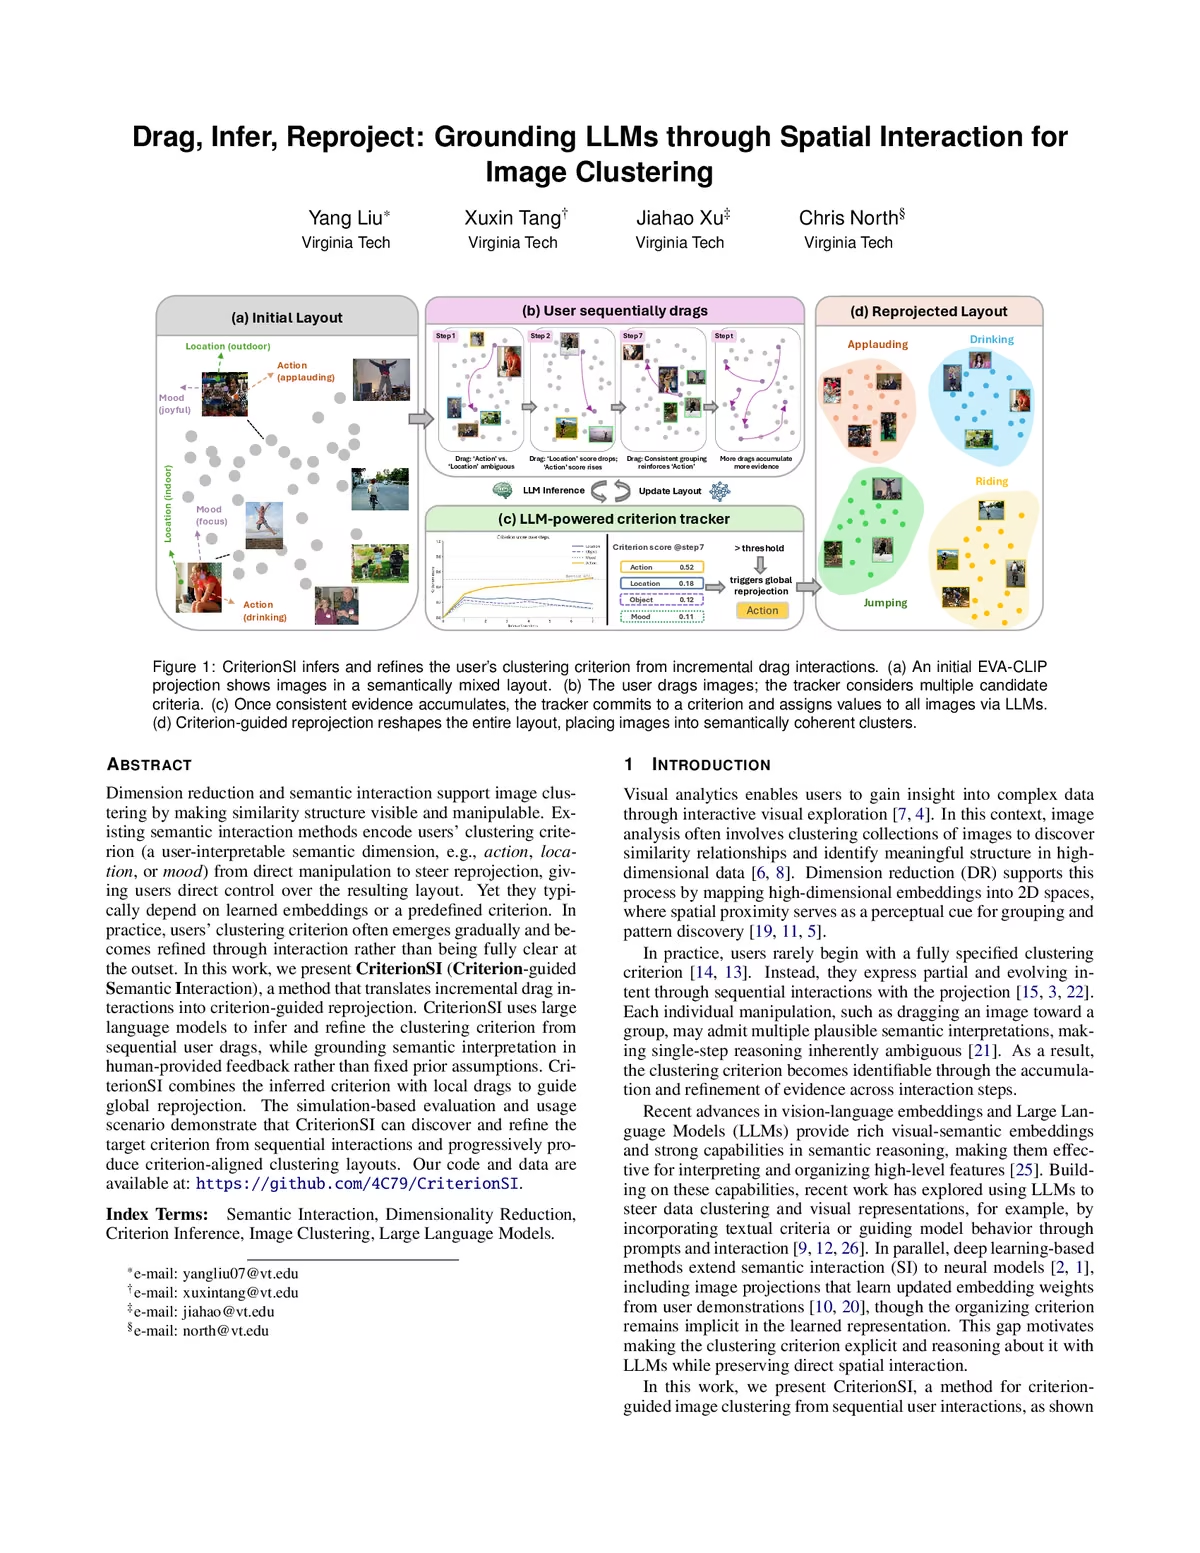
Dimension reduction and semantic interaction support image clustering by making similarity structure visible and manipulable. Existing semantic interaction methods encode users' clustering criterion (a user-interpretable semantic dimension, e.g., action, location, or mood) from direct manipulation to steer reprojection, giving users direct control over the resulting layout. Yet they typically depend on learned embeddings or a predefined criterion. In practice, users' clustering criterion often emerges gradually and becomes refined through interaction rather than being fully clear at the outset. In this work, we present CriterionSI (Criterion-guided Semantic Interaction), a method that translates incremental drag interactions into criterion-guided reprojection. CriterionSI uses large language models to infer and refine the clustering criterion from sequential user drags, while grounding semantic interpretation in human-provided feedback rather than fixed prior assumptions. CriterionSI combines the inferred criterion with local drags to guide global reprojection. The simulation-based evaluation and usage scenario demonstrate that CriterionSI can discover and refine the target criterion from sequential interactions and progressively produce criterion-aligned clustering layouts. Our code and data are available at: https://github.com/4C79/CriterionSI.
For Practitioners
This paper will interest visualization and visual analytics tool builders, human-AI interaction researchers, and practitioners who organize image collections by meaning rather than appearance, including data scientists and designers. They can adopt the core pattern: treat each drag as evidence of a latent organizing criterion, let an LLM infer, stabilize, and name it, then propagate it across the whole collection.